The role
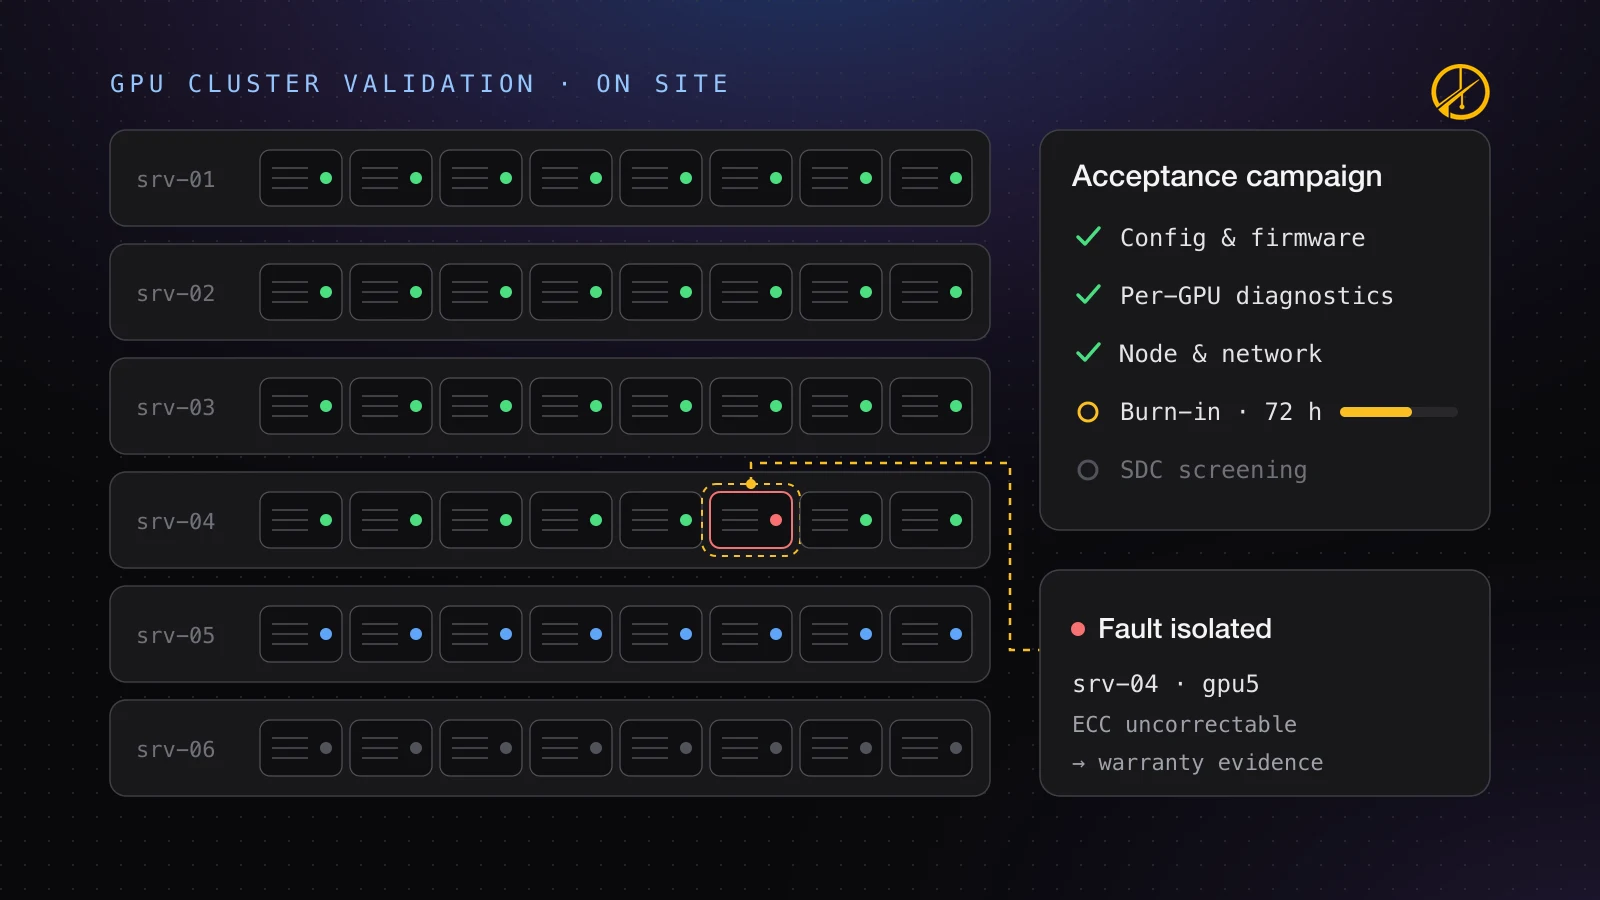
Before a customer puts hundreds of 8-GPU servers into production, we test every server and every GPU, find the faulty hardware, and give the customer evidence they can use for warranty replacement. We are looking for an engineer to run that work on site.
On site, you bring up our test platform on the customer's cluster and confirm that servers, networks, drivers, firmware, power and cooling are ready for every machine to run at full load at once. You run the test campaign across hundreds of servers: version and configuration checks, per-GPU diagnostics and performance, node and network tests, storage and thermal checks, multi-day burn-in and silent-data-corruption screening. When something fails, you reproduce it, separate a real hardware fault from a configuration or software problem, and isolate the faulty GPU, cable, NIC or server.
Engagements run one to four weeks at customer data centers, with regular travel between them. The position is full-time or contract.